
Cybersecurity
Israeli VC in Cybersecurity, Deep Tech and Defense: A Deep Dive

| Key Takeaways
• Israeli cybersecurity companies raised $4.1 billion in private funding in 2025, with a median round of $20 million, double the business software median. • About 1,500 deep-tech companies operate in Israel and have raised $28.6 billion since 2019, roughly 35% of all capital raised by Israeli high-tech. • Israeli companies raised more than 20% of all deep-tech capital invested in the cyber sector worldwide, according to the Israel Innovation Authority. • Google’s $32 billion acquisition of Wiz and Palo Alto Networks’ $25 billion purchase of CyberArk led a record $74.3 billion in Israeli tech M&A in 2025. |
Why do Israeli VCs concentrate on cybersecurity?
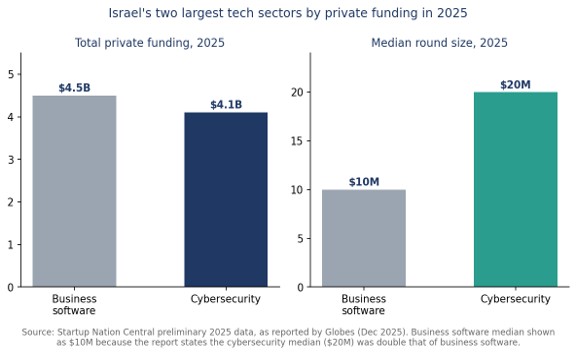
Israeli VCs concentrate on cybersecurity because it is the sector where Israel commands the largest share of global capital and produces the largest rounds. Israeli cybersecurity companies raised $4.1 billion in private funding in 2025, according to preliminary Startup Nation Central data, and their median round reached $20 million, double the median in business software.
The concentration is not only a local story. The Israel Innovation Authority reports that Israeli companies raised more than 20% of all deep-tech capital invested in the cyber sector worldwide. For an investor, that combination of a dense founder pool, repeat entrepreneurs and an established buyer base among global security vendors creates a deal flow that is difficult to replicate in most other markets.
This is why a typical Israeli VC with a security thesis now positions cyber alongside AI, deep tech and defense tech rather than as a standalone category. Security problems increasingly sit inside AI systems, cloud infrastructure and physical networks, so the investment thesis has widened with them.
How does deep tech change the Israeli VC model?
Deep tech changes the Israeli VC model by requiring more capital, longer holding periods and deeper technical diligence than software investing. The Israel Innovation Authority defines deep tech by high technological risk and a long time to market, conditions it notes can make it harder for these companies to raise money.
The sector has nonetheless become one of the country’s strongest. Joint research by the Israel Innovation Authority and Dealroom counts about 1,500 active deep-tech companies in Israel that have raised $28.6 billion since 2019, roughly 35% of all capital raised by Israeli high-tech over that period. The cumulative valuation of private Israeli deep-tech companies has passed $177 billion, about 15 times higher than a decade earlier, and the report places Israel as the leading deep-tech fundraising hub in the Western world outside the United States. The full findings are summarized in the Israel Innovation Authority’s 2025 status report.
For investors, the practical consequence is that a deep-tech round is rarely judged on revenue alone. Diligence turns to physics, materials, manufacturing readiness and certification paths, and the investor needs reserves to support the company through a longer development cycle before commercial scale.
What is driving investor interest in defense and dual-use technology?
Rising defense budgets are the main driver of investor interest in defense and dual-use technology, because they create large, durable demand for capabilities that often transfer later into civilian markets. Global military spending reached about $2.7 trillion in 2025, and roughly $19 billion flowed into aerospace and defense startups that year, nearly double the $10 billion raised in 2024, according to figures compiled in an analysis of defense spending as a deep tech catalyst.
That same analysis argues that technologies such as AI, quantum sensing and advanced robotics are often tested and hardened in defense environments before moving into commercial use. It also notes that hardware-heavy companies need larger upfront capital and closer coordination with industrial and government partners than software startups, which is pushing venture investors to work more closely with private equity as companies move toward production.
The same piece flags post-quantum security as an emerging area, pointing to the risk that data encrypted today can be harvested now and decrypted later once quantum computing matures, and to a quantum security market projected to grow at nearly 45% a year through 2029. For an Israeli VC with roots in both cyber and defense, post-quantum work sits directly at the intersection of its two strongest fields.
Dual-use positioning matters to an Israeli VC because it widens the exit map. A company whose technology serves both defense buyers and commercial customers can be acquired by a defense prime, a civilian technology company or an industrial group, rather than depending on a single type of acquirer.
How do CISO networks give Israeli cyber investors an edge?
CISO networks give Israeli cyber investors an edge by putting the eventual buyers of a security product into the room before the product is finished. A chief information security officer can tell a founder within one meeting whether a problem is urgent, whether it already has a budget line, and which existing tools the new product would need to replace.
Some Israeli investors have formalized this into a structure. One example is a CISO-led investment alliance that operates as a cybersecurity micro fund and brings together security leaders from large global organizations to validate, guide and support early-stage companies. Investors with this kind of network typically build a cybersecurity portfolio spanning cloud, identity and threat detection, along with data, endpoint and network security, because practitioner feedback points them toward the categories where enterprise demand is forming.
What do recent exits reveal about Israeli VC returns in cyber?
Recent exits show that Israeli cybersecurity companies can command some of the largest acquisition prices in global technology. Google’s $32 billion acquisition of Wiz and Palo Alto Networks’ $25 billion purchase of CyberArk led a record $74.3 billion in M&A involving Israeli tech companies in 2025, across 150 transactions.
Exits of that size reset expectations for the entire funding chain. Limited partners see proof that capital can come back at scale, later-stage investors become more willing to pay up for category leaders, and early-stage investors can justify larger seed and Series A checks. Earlier coverage of early-stage defense innovation in cybersecurity venture capital looks at how this dynamic plays out for younger security companies.
What should founders look for in an Israeli VC in these sectors?
Founders in cyber, deep tech and defense tech should look for an Israeli VC with domain-specific partners, reserves for a longer development cycle and access to real customers or test environments. Generalist capital can fund a round, but it rarely shortens the time it takes to reach a credible first deployment.
Useful questions include whether the partners have operated inside security teams or defense R&D organizations, how much the fund typically reserves for follow-on rounds, and whether its strategic partners can provide pilots with real data in live environments. For dual-use companies, it also helps to ask how the investor approaches export controls and government procurement cycles, since both affect timelines and valuation.
Frequently Asked Questions
Why is Israel so strong in cybersecurity startups?
Israel has a dense pool of experienced security founders and a strong buyer base among global vendors, and Israeli companies raised more than 20% of all deep-tech capital invested in the cyber sector worldwide, according to the Israel Innovation Authority.
How much do Israeli cybersecurity startups raise per round?
The median private funding round for Israeli cybersecurity companies was $20 million in 2025, double the median for business software companies, according to preliminary Startup Nation Central data.
What counts as deep tech in Israel?
The Israel Innovation Authority describes deep-tech companies as those developing complex technology with high technological risk and a long time to market; about 1,500 such companies operate in Israel.
Do Israeli VCs invest in defense technology?
A growing number of Israeli VCs invest in defense and dual-use technology, focusing on companies whose products can serve both defense and civilian markets as global defense budgets rise.

| Key Takeaways
• Homegrown AI application security protects AI tools an organization builds itself, including internal copilots, RAG assistants, and custom agents, along with the data and systems they can reach. • IBM’s Cost of a Data Breach Report 2025 found that 13% of organizations reported breaches of AI models or applications, and 97% of those breached lacked proper AI access controls. • Prompt injection, sensitive information disclosure, and excessive agency rank first, second, and third in the OWASP Top 10 for LLM Applications 2026 edition. • Effective programs combine design-time controls such as least-privilege retrieval with runtime monitoring and policy enforcement across every internal AI app. |
What is homegrown AI application security?
Homegrown AI application security is the practice of protecting AI applications an organization builds itself, such as internal copilots, retrieval-augmented generation (RAG) assistants, and custom agents, from data leakage, prompt manipulation, and misuse of the systems those applications can reach. It differs from securing public AI tools like consumer chatbots because the organization owns the whole stack: the prompts, the retrieval pipeline, the connected databases, and the permissions the application holds.
That ownership is both the opportunity and the burden. A team that ships an internal assistant over the company wiki, ticketing system, and CRM has effectively built a new privileged application, often in weeks rather than the months a traditional enterprise system would take. As a broader analysis of how internally built AI apps now behave like enterprise software argues, these tools deserve the same security rigor as any other production system that touches sensitive data. That is the premise behind dedicated homegrown AI application security programs, which treat every internal assistant as a governed asset from the day it ships.
How often are custom AI applications actually breached?
In IBM’s Cost of a Data Breach Report 2025, 13% of organizations reported breaches of AI models or applications, and another 8% did not know whether they had been compromised in this way. The research, conducted by the Ponemon Institute across 600 organizations that experienced breaches between March 2024 and February 2025, was the first edition of the report to study security and governance for AI specifically.
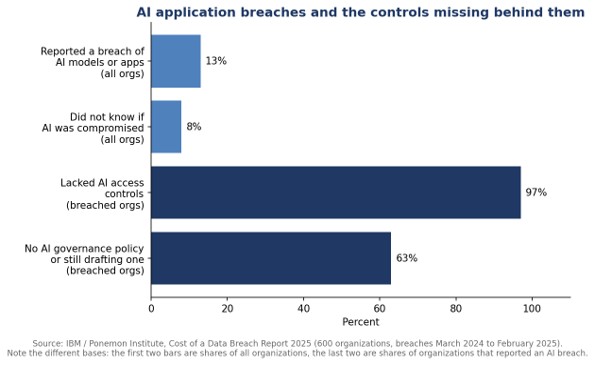
The more telling numbers sit behind the headline. Among organizations that reported an AI-related breach, 97% said they lacked proper AI access controls, and 63% either had no AI governance policy or were still developing one. Independent coverage of the 2025 breach report findings on AI governance also noted that among organizations with AI governance policies, only 34% perform regular audits for unsanctioned AI. The pattern is consistent: the failures are less about exotic model attacks and more about missing basic controls around who and what can reach an AI application.
Which risks matter most for internally built AI apps?
The risks that matter most for internally built AI apps are prompt injection, sensitive information disclosure, and excessive agency, which hold the top three positions in the 2026 edition of the OWASP Top 10 for LLM Applications. Each one maps directly onto a common homegrown design choice. RAG pipelines pull in documents an attacker may be able to edit, which opens the door to injection. Broad retrieval permissions let a user ask the assistant for data they could never open directly. Tool integrations let the application send email, update records, or run queries on its own.
The OWASP Top 10 for LLM Applications remains the most practical checklist for teams building their own AI applications because it describes risks in terms of application design rather than model internals, which is exactly the layer an internal development team controls.
What are the best approaches to securing a homegrown AI app?
The best approaches to securing a homegrown AI app combine design-time controls, such as least-privilege retrieval and input segregation, with runtime controls, such as monitoring prompts and responses and enforcing data policies as the application runs. No single control is sufficient, because many attacks on AI applications succeed by chaining small weaknesses together. The table below compares the main approaches and where each one helps.
| Approach | What it protects against | Main limitation |
| Pre-deployment testing and red teaming | Known prompt injection patterns and unsafe outputs before launch | Cannot anticipate every input the app will see in production |
| Least-privilege retrieval and tool access | Users or attackers reaching data and actions beyond their role | Requires mapping permissions for every connected data source |
| Input and output filtering | Sensitive data leaving in responses; obvious malicious instructions | Static rules miss novel or encoded attacks |
| Runtime monitoring and policy enforcement | Live misuse, data leakage, and anomalous agent behavior | Needs tuning so that alerts reflect real risk rather than noise |
| Governance and inventory | Unknown or abandoned AI apps with no owner | Only effective if the inventory is kept current |
Runtime coverage is where many programs remain thinnest. Testing describes how an application behaved on the day it was evaluated, while runtime controls describe how it behaves every day after that. Teams evaluating runtime platforms typically look for real-time visibility into prompts, responses, and data flows across every internal AI app, plus the ability to apply policy without rewriting each application. Ovalix is one example of this approach: its homegrown AI application security continuously tracks user inputs, model behavior, and data flows inside custom AI apps and applies governance rules across every AI endpoint automatically.
Sequencing matters as much as selection. Teams that start with inventory and least-privilege access usually find their highest-risk applications quickly, because the apps with the broadest retrieval permissions and the most tool integrations are almost always the ones that need runtime controls first. Testing and red teaming then become more targeted, focused on the specific data sources and actions each application can actually reach, rather than generic prompt lists run against every assistant in the same way.
How do you stop data leakage from a custom AI application?
Stopping data leakage from a custom AI application requires controlling what the application can retrieve, inspecting what it returns, and logging both so that leaks can be detected and traced. Classic data loss prevention tools struggle here because AI responses paraphrase and summarize rather than copy, so a pattern match on a document’s exact text will often miss a model’s rewording of it. Data loss prevention adapted for AI addresses that gap by evaluating meaning and context rather than exact strings.
A related analysis of GenAI data leakage prevention in the enterprise reaches a similar conclusion: leakage prevention for AI works best when it is applied at the point where data enters and leaves the model, not only at the network perimeter.
Who should own security for internal AI apps?
Security for internal AI apps works best as a shared responsibility in which the building team owns secure design and the security team owns visibility, policy, and runtime enforcement across all AI applications. Without that split, two failure modes are common. Either each product team invents its own controls, producing inconsistent protection, or security reviews every app by hand, which cannot keep pace with how quickly new assistants are built.
A useful starting point is agreeing on what counts as a homegrown AI app in the first place. Ovalix’s glossary, for instance, defines the category broadly, covering internal apps that retrieve enterprise data, connect to APIs, plugins, and MCP servers, and trigger workflows, and lists prompt injection, sensitive data leakage, insecure integrations, and excessive agency among their core risks. A definition that wide ensures that every internal assistant, agent, and AI-powered workflow lands in the same inventory and inherits the same baseline controls from day one.
Frequently Asked Questions
What is a homegrown AI application?
A homegrown AI application is an AI-powered tool an organization builds for its own use, such as an internal assistant, a RAG-based search tool, or a custom AI agent connected to company data and systems.
Is securing a homegrown AI app different from securing ChatGPT use?
Yes. Securing public AI tools focuses on what employees share with an external service, while securing a homegrown AI app also covers the retrieval pipeline, connected data sources, and permissions the organization itself built.
What is the biggest security risk for internal AI apps?
Prompt injection is ranked the top risk in the OWASP Top 10 for LLM Applications 2026 edition, followed by sensitive information disclosure and excessive agency, all of which apply directly to internal AI apps.
How many organizations have had an AI application breach?
IBM’s Cost of a Data Breach Report 2025 found that 13% of organizations reported breaches of AI models or applications, and 97% of those breached lacked proper AI access controls.
| Key Takeaways
• Adaptive AI agents pursue goals rather than fixed scripts, so their risk appears at runtime rather than in a static configuration file or access list. • An AI agent can expose sensitive data without violating any access control, simply by combining information it is permitted to reach in ways no one anticipated. • In the 2025 OWASP Top 10 for LLM Applications, Sensitive Information Disclosure rose to second place and Excessive Agency was expanded to cover agentic architectures. • Behavioral baselines define risk by deviation from an agent’s normal activity, which lets security intervene precisely without shutting the agent down. |
What makes an AI agent “adaptive”?
An adaptive AI agent is given a goal rather than a fixed script, so it evaluates context, chooses which tools to call and changes its behavior based on live data. That flexibility is what makes adaptive AI agents useful for real business work, and it is also what makes them hard to secure with controls designed for predictable software.
Traditional automation follows defined triggers and produces repeatable outcomes. An adaptive agent built in an enterprise copilot platform, a CRM or an internal-tool builder does not. It may query a different data source tomorrow than it did today, combine information in ways its builder never tested, or respond to an input that was never part of the original design. The security question therefore moves from “what is this agent allowed to do?” to “is what it is doing right now appropriate?”
Why do static, rule-based controls miss agent risk?
Static controls miss agent risk because they assume systems are centrally owned, behave predictably and can be fully assessed before deployment, and adaptive AI agents break all three assumptions. Pre-deployment reviews, access control enumeration, manual approval gates and periodic audits were built for software that changes on a release schedule, not for agents whose behavior shifts with every conversation.
A widely discussed example illustrates the gap between permission and behavior. An internal assistant is built on a business platform and connected through approved connectors. An employee with limited privileges chats with it, and through conversation alone the agent retrieves and synthesizes information that employee could not access directly. No access control is violated and no policy is technically broken, yet sensitive data has moved somewhere it should not. The risk did not live in the configuration. It appeared at runtime.
Which OWASP risks matter most for adaptive AI agents?
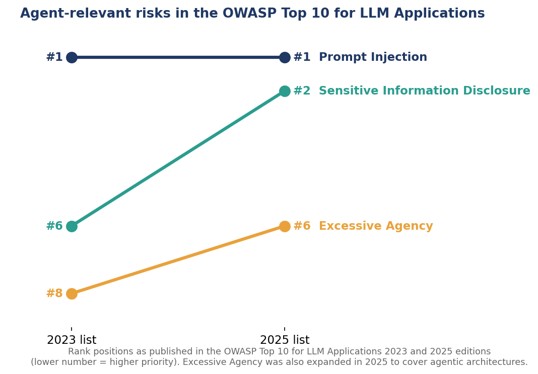
Three entries in the OWASP Top 10 for LLM Applications matter most for adaptive AI agents: Prompt Injection, Sensitive Information Disclosure and Excessive Agency. In the 2025 edition, Prompt Injection stayed at number one, Sensitive Information Disclosure rose from sixth to second, and Excessive Agency moved from eighth to sixth and was expanded to cover agentic architectures.
OWASP’s definition of Excessive Agency describes it as the vulnerability that enables damaging actions in response to unexpected, ambiguous or manipulated model outputs, whatever caused the model to malfunction. OWASP traces the root cause to one or more of three factors: excessive functionality, excessive permissions and excessive autonomy. The 2025 guidance also acknowledges that no fool-proof prevention for prompt injection is currently known, which is a strong argument for controls that watch what an agent actually does rather than relying only on filtering what goes into it.
How does a behavioral baseline work for an AI agent?
A behavioral baseline is a profile of an agent’s normal activity, built by observing what data it typically accesses, which tools it calls, who interacts with it and how often it runs. Once the baseline exists, security defines risk by deviation rather than entitlement: an action is suspicious because it is abnormal for that specific agent, not because it is outside a list someone wrote in advance.
This approach usually runs as a four-stage loop. The system first learns each agent’s behavior and context. It then enforces existing security policies as living rules that apply automatically. Third, it detects anomalies against each agent’s own profile, which is more precise than a single threshold applied to every agent. Finally, it prevents risky or noncompliant agents from acting or activating. Importantly, the adaptive layer extends predefined rules rather than replacing them, so existing policies stay in force while coverage expands to edge cases nobody anticipated.
What does runtime enforcement look like without breaking the agent?
Runtime enforcement uses narrow, targeted interventions, such as pausing a single high-risk query, requiring step-up validation for an unexpected action or blocking anomalous outbound traffic, while the agent’s legitimate functions keep running. The goal is to stop the specific harmful action, not to switch the agent off.
In practice, adaptive runtime protection for AI agents focuses on three threat categories. Prompt injection and manipulation covers instructions smuggled in through user input, documents or connected data. Data leakage covers sensitive information flowing to a destination it should not reach. Command abuse covers tools being misused, misfired or misinterpreted by the agent. Each intervention should also alert the agent’s owner with enough context to fix the underlying issue, so the same anomaly does not repeat the next day.
Static rules vs adaptive guardrails: how do they compare?
Static rules are precise for known risks, while adaptive guardrails cover the unknown behavior that emerges once agents meet real users and data, so mature programs use both. The comparison below summarizes how each approach handles the same problems.
| Question | Static, rule-based controls | Adaptive guardrails |
| When is risk assessed? | Before deployment and at periodic audits | Continuously, while the agent runs |
| What defines a violation? | An action outside predefined permissions | An action that deviates from the agent’s normal behavior |
| Coverage of new behavior | Only what rule authors anticipated | Extends to edge cases and novel patterns |
| Typical response | Block, or allow and log | Pause, require step-up validation, block, or alert the owner |
| Effort as agents multiply | Grows with every new agent and rule | Profiles are learned per agent automatically |
Where does adaptive protection fit in the agent development lifecycle?
Adaptive protection covers the runtime stage of the agent development lifecycle, the last of four stages that run from design and build through deployment and runtime. Each stage needs its own controls, in the same way any enterprise application does.
Design and build are where builders choose data sources, tools and permissions, and where least privilege does the most good. Deployment is where approval gates and configuration checks belong. Runtime is where adaptive AI agents reveal behavior that no earlier stage could predict. A whitepaper on runtime controls for enterprise agents frames this as a shift from asking whether a system has access to asking whether an action is appropriate in its current context, and lays out a four-step path for getting there.
For security teams, the practical takeaway is to stop treating approval as the finish line. Agents built by business users will keep evolving after they are approved, and the controls protecting them need to evolve at the same speed.
Frequently Asked Questions
What is an adaptive AI agent?
An adaptive AI agent is an AI system given a goal instead of a fixed script, which evaluates context and chooses its own actions and tools based on live data.
Why are traditional security controls not enough for AI agents?
Traditional controls assess risk before deployment and assume predictable behavior, while AI agents change how they act at runtime, so an agent can stay within its granted permissions and still expose sensitive data.
What is Excessive Agency in AI security?
Excessive Agency is an OWASP Top 10 for LLM Applications risk in which an AI system can take damaging actions because it has excessive functionality, excessive permissions or excessive autonomy.
Do adaptive guardrails replace rule-based security policies?
No, adaptive guardrails extend rule-based policies by learning each agent’s normal behavior and flagging deviations, while predefined rules continue to enforce known requirements.
| Key Takeaways
• Independent security researchers found that Power BI’s “Publish to Web” feature has exposed sensitive data at tens of thousands of organizations worldwide. • A broad search-engine query for publicly indexed Power BI report URLs returned over 160,000 results, narrowing to over 50,000 with refined search terms. • Unauthorized users can reach a report’s underlying semantic model, including hidden tables and filtered records, through direct API calls even when the visible report looks anonymized. • Microsoft characterized the underlying behavior as a design choice rather than a vulnerability, meaning the responsibility for avoiding exposure falls on the organization publishing the report. |
How do Power BI reports end up exposing sensitive data publicly?
Power BI reports end up exposing sensitive data publicly most often through the platform’s “Publish to Web” feature, which is designed to make a report freely viewable by anyone with the link, but which independent security researchers found also frequently exposes far more than the report’s visible summary. An account of how Microsoft Power BI reports have exposed sensitive data on the web describes how unauthorized users can reach the underlying semantic model behind a published report, including hidden tables, filtered records, and columns that were deliberately left out of the visible dashboard, through straightforward API calls that don’t require any special access.
That distinction matters: an organization might reasonably believe it published only an anonymized summary chart, while the data actually sitting behind that chart, unaggregated and unfiltered, remains reachable to anyone who knows where to look. The gap between what a report appears to show and what its underlying model actually contains is the core of why this has become a recurring exposure pattern rather than a one-off configuration mistake.
Researchers described the extraction process itself as simple: once a published report is located, pulling the hidden data behind it doesn’t require credentials, special tooling, or any interaction with the organization that published it. That combination, a low technical bar paired with a large and easily searchable pool of published reports, is what turned this from a theoretical design tradeoff into a practical exposure risk that researchers could demonstrate at scale rather than in a single isolated case.
How widespread is this Power BI exposure problem?
Independent security researchers reported that the issue affects tens of thousands of organizations worldwide, after finding that a simple search-engine query for publicly indexed Power BI report URLs returned more than 160,000 results, a number that narrowed to over 50,000 with more targeted search terms. Manually screening a portion of those results, researchers said they quickly identified dozens of reports from which sensitive data, including employee records, customer information, and government data, could be extracted, with some belonging to state government sites, universities, and municipalities.
The categories of exposed data researchers documented included protected health information and personally identifiable information alongside internal business records, which is a meaningfully different risk profile than the marketing dashboards and public statistics the “Publish to Web” feature was originally intended for. Because the exposure sits at the semantic-model level rather than in the visible chart, standard checks like reviewing what’s on-screen in a published report simply won’t catch it; the risk lives one layer below what anyone looking at the report would ever see.
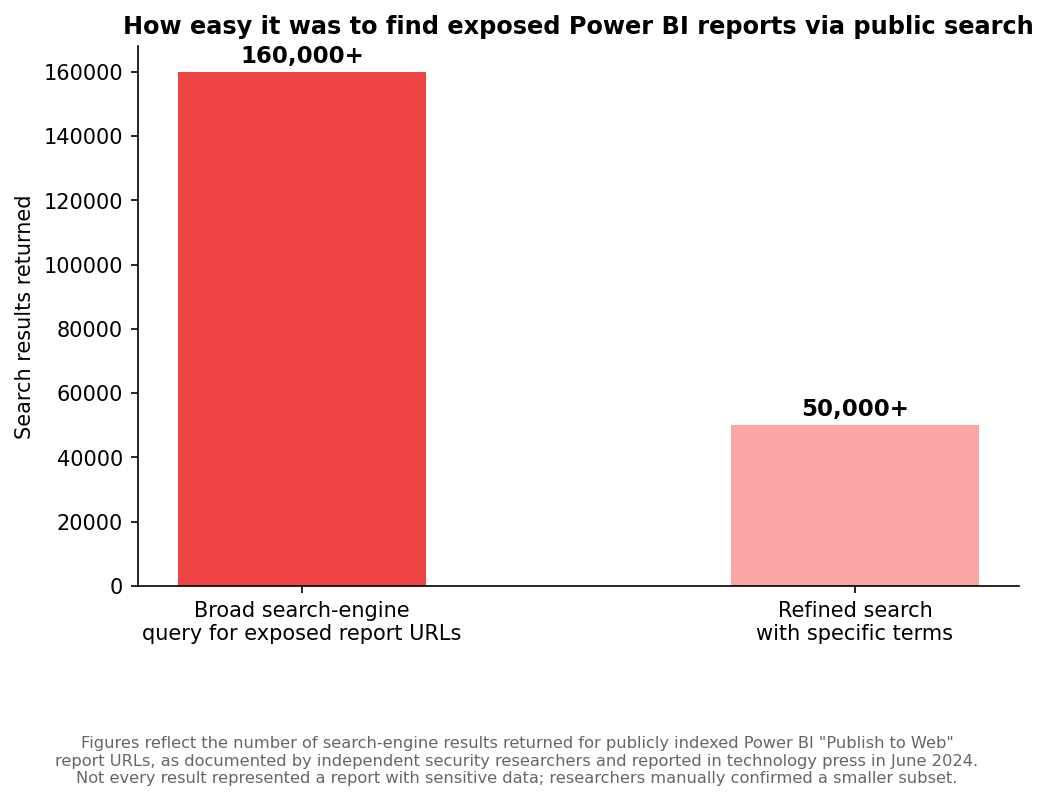
Figures reflect the number of search-engine results returned for publicly indexed Power BI “Publish to Web” report URLs, as documented by independent security researchers and reported in technology press in June 2024. Not every result represented a report with sensitive data; researchers manually confirmed a smaller subset.
What did Microsoft say when researchers reported the issue?
Microsoft’s Security Response Center confirmed the underlying behavior but characterized it as a design choice rather than a vulnerability, after researchers reported the issue in mid-2024. That framing puts the responsibility for avoiding exposure squarely on the organization publishing the report, which is consistent with how Microsoft’s own documentation on publishing Power BI reports to the web describes the feature: it’s intended for content meant to be fully public, and Microsoft advises against using it for anything containing information that shouldn’t be visible to an anonymous internet user. In practice, that guidance is easy to miss in the moment someone clicks “publish” to quickly share a dashboard with a client or a public audience, especially when the person doing the sharing is focused on the visible chart and has no reason to think about what else might be attached to it underneath.
Does this risk stop at Power BI, or does it extend across the Power Platform?
It extends well beyond Power BI. A breakdown of the Power Platform’s broader security risk surface identifies five recurring threat categories across the platform family: Power Apps exposure and hardcoded secrets, Power Automate flows carrying injection and stale-credential risk, Power BI dashboards oversharing data, custom connectors introducing supply-chain risk from untrusted sources, and Copilot Studio agents taking unvetted actions through unsafe integrations. Power BI’s publish-to-web exposure is simply the most visible and most publicly documented instance of a pattern that shows up across the whole platform: features built for ease of sharing and automation, deployed by people who aren’t necessarily thinking about the security implications of a single click.
What should an organization actually do about exposed or overshared reports?
The first step is knowing what’s already been published, since most organizations don’t have a running inventory of every report or dashboard that’s been shared externally, let alone what data sits behind each one. A use case built around detecting overshared and publicly exposed data across connected platforms approaches this by mapping data sources, connectors, and integrations tied to each app, flow, and report, then flagging assets that are publicly exposed or that have accumulated more access than their intended audience should have. From there, remediation is usually straightforward: unpublish or reconfigure the report, and route a notification to whoever owns it so the same mistake doesn’t get repeated the next time a quick external share feels like the fastest option.
The underlying lesson generalizes past Power BI specifically. Any platform feature designed to make sharing effortless is, by definition, also a feature that makes oversharing effortless, and the organizations that catch these exposures early are the ones actively looking for them rather than waiting for a researcher, or an attacker, to find them first.
There’s also a timing argument for treating this as an ongoing check rather than a one-time cleanup. New reports get published continuously as teams share dashboards with clients, partners, or the public, so a single audit that clears the current backlog doesn’t prevent the next well-intentioned share from recreating the same exposure a month later. Building the check into a recurring process, rather than a project with a defined end date, is what keeps the fix durable instead of temporary.
Frequently Asked Questions
Can someone access hidden data in a Power BI report even if it looks anonymized?
Yes. Security researchers demonstrated that unauthorized users can reach hidden tables, filtered records, and non-displayed columns in a report’s underlying semantic model through direct API calls, even when the visible report appears to show only an aggregated summary.
Did Microsoft treat the Power BI exposure as a security vulnerability?
Microsoft’s Security Response Center confirmed the behavior after it was reported but characterized it as a design choice rather than a vulnerability, placing responsibility on the organization publishing the report to avoid including sensitive information.
Is this exposure risk limited to reports published with “Publish to Web”?
The most widely documented cases involve “Publish to Web,” but the broader Power Platform carries similar oversharing and exposure risks across Power Apps, Power Automate, custom connectors, and Copilot Studio agents.
How can an organization find out if it has exposed Power BI reports already published?
Organizations typically need an inventory of every report, dashboard, and connector that has been published or shared externally, since most do not track this automatically and can’t remediate exposure they don’t know exists.

Should B2B Brands Optimize for Specific AI Engines? How ChatGPT, Google, Perplexity, and Claude Compare

What Is a Blow Molded Case? Process, Materials and Trade-offs Explained

Delay Lines Compared: Coaxial, Acoustic, Digital and Fiber Optic Options for RF Systems

-
 Business Solutions2 years ago
Live Video Broadcasting with Bonded Transmission Technology
-
 Business Solutions1 year ago
The Future of Healthcare SMS and RCS Messaging
-
 Business Solutions2 years ago
2-Way Texting Solutions from Company Message Services
-
 Business Solutions2 years ago
Communication with Analog to Fiber Converters & RF Link Budgets
-
 DSRC Communication2 years ago
The Crossroads of Connectivity: DSRC vs. C-V2X Technologies in Automotive Communication
-
 Business Solutions2 years ago
Wholesale SMS Platforms with OTP Services
-
 Business Solutions2 years ago
Choosing the Right B2B Digital Marketing Agency: A Guide
-
 3D Technology2 years ago
How Multispectral Cameras Advance Book Scanning