
Tech
Power BI Security: How Exposed PowerBI Reports Leak Sensitive Data

|
Key Takeaways
|
What is the Power BI data exposure issue, exactly?
Every Power BI report is built on top of a semantic model, which represents all the data that could be used for visualization, while the report itself defines which data actually becomes visible in the interface and how. The problem is that when a report is shared, whether explicitly or implicitly by sharing the workspace it lives in, the entire underlying semantic model becomes accessible too, not just the parts a viewer can see on screen. That includes detailed records behind aggregated numbers, tables marked “hidden” in the model, non-displayed columns of visible tables, and detailed records that a report’s own filters were supposed to exclude.
Why does hiding a table or column in Power BI not actually secure it?
This is the part that catches most report owners off guard. Kanopy Security’s research into this exposure found that Power BI’s query API doesn’t check whether a table or column has been marked hidden before returning it; a user can request the name of a hidden “secrets” table, or ask for a column excluded from every visual, and the underlying query engine will return it anyway, as long as that table or column exists somewhere in the semantic model the report is built on. The behavior affects reports shared internally within an organization just as much as reports published openly to the web.
How large is the publicly exposed PowerBI surface, really?
Because so many organizations publish Power BI reports to the open web for legitimate reasons, sharing dashboards with customers, partners, or the public, that publishing habit alone creates a large attack surface once this exposure issue is factored in. A simple search engine query targeting Power BI’s public report URL pattern returns well over 160,000 results, and narrowing that query toward a specific business topic, such as adding a keyword like “sales”, can still return tens of thousands of more targeted matches.
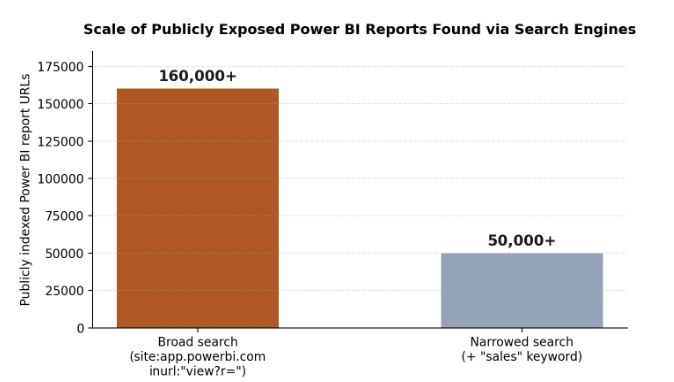
Publicly indexed Power BI report URLs found via a broad search engine query versus a topic-narrowed query.
Not every one of those results is exploitable, plenty are sample reports created by consultants or service providers to demonstrate their own skills. But manual review of even a small, randomly sampled subset of real organizational reports turns up genuine examples: state government sites unintentionally exposing protected health information, universities exposing employee data, and municipalities exposing personally identifiable information, all through reports their owners likely assumed were safely aggregated or filtered.
Does Microsoft consider this a vulnerability?
No, and that distinction matters for how organizations need to respond. Microsoft was notified through its official vulnerability disclosure channel and confirmed the behavior within two days, but classified it as a feature rather than a vulnerability, which independent reporting on the issue also noted at the time, describing how Microsoft’s stance leaves report owners themselves responsible for configuring semantic models securely, since no patch addressing the underlying behavior should be expected.
How does the exploit actually work, technically?
Running a Power BI report requires an API call that fetches the data to be displayed, a request sent to one of Power BI’s query endpoints depending on whether the report is public or restricted to an organization. The request payload is a query, in Power BI’s own proprietary format, specifying which columns and tables to retrieve, and the response returns that data as JSON. Because the query API doesn’t check whether a requested column or table is marked hidden in the semantic model, a user can simply ask for a hidden table by name and receive its contents. A separate API call, used internally to help generate the report itself, can also be used to enumerate the entire semantic model’s schema, including hidden tables and columns, giving anyone who wants to explore a report’s underlying data a roadmap for exactly what to ask for.
What kinds of organizations have been found exposed?
Manual review of a sample of publicly indexed reports turned up real examples across very different sectors, which underscores that this isn’t a niche risk limited to one industry:
- State government sites, unintentionally exposing protected health information (PHI) through reports meant to share only aggregate public health statistics.
- Universities, exposing employee data through reports intended to show only summarized institutional metrics.
- Municipalities, exposing personally identifiable information (PII) through reports built to share only anonymized community data.
- Commercial organizations, sharing what they believed were safely filtered sales, financial, or operational dashboards with partners or the public.
In each case, the organizations involved almost certainly believed their reports were safe to share, since the visible dashboard showed only the aggregated or filtered view they intended. The underlying semantic model told a different story.
What actually needs to change to fix exposed PowerBI reports?
| Common mistake | What to do instead |
|---|---|
| Marking a table or column “hidden” in the model | Remove it from the semantic model entirely rather than relying on the hidden flag, which the query API ignores. |
| Filtering sensitive rows only in the report’s visuals | Restrict the data source itself using a Power Query expression, so filtered rows are never part of the semantic model to begin with. |
| Aggregating sensitive columns only in the display | Aggregate the data at the data source level, or exclude sensitive columns from the semantic model before it reaches the report. |
| Assuming a one-time review is sufficient | Audit Power BI environments regularly for reports that were published to the web unintentionally or overshared internally. |
How can an organization check its own exposure?
Because this isn’t a bug that gets patched centrally, checking exposure has to happen at the organization level. Kanopy Security’s data leakage prevention capability continuously monitors data usage patterns across business-built platforms, including Power BI, surfacing risky sharing configurations and unexpected data movement as they happen rather than waiting for a periodic audit to catch them. For a quicker, self-directed first check, Kanopy also released the Power BI Analyzer, a free, open source scanning tool that reviews an organization’s Power BI environment for reports published to the web or widely shared internally, then flags any that carry more underlying data than the report actually displays.
- Start with reports published to the web, since they carry the highest exposure risk to anyone who finds the URL.
- Check for hidden tables and columns specifically, since “hidden” in Power BI’s UI does not mean inaccessible through its API.
- Review widely shared internal reports too, since the same exposure applies to anyone with access to the workspace, not just the public web.
- Repeat the audit on a schedule, since new reports get published continuously and a one-time review goes stale quickly.
Frequently Asked Questions
What is the Power BI data leakage vulnerability that Kanopy Security discovered?
A flaw in how Power BI reports work: every report runs on a semantic model holding all the underlying data, but when a report is shared or published to the web, the entire semantic model, including hidden tables, hidden columns, and filtered-out records, stays accessible through Power BI’s own query API, even though none of it appears in the visible report.
Does Microsoft consider the Power BI data exposure a vulnerability?
No. Kanopy reported the issue to the Microsoft Security Response Center on May 16, 2024, and Microsoft confirmed the behavior two days later, on May 18, 2024, but classified it as a feature, not a vulnerability. That means no fix is coming, and it falls to report owners to configure their semantic models securely.
How can an organization check if its Power BI reports are exposing hidden data?
Kanopy Security built and open-sourced a free tool, the Power BI Analyzer, which scans an organization’s Power BI environment for reports published to the web or widely shared internally, then flags any that carry more underlying data than what the report actually shows.
How can I stop my Power BI reports from leaking hidden data?
Remove hidden tables and columns from the semantic model entirely rather than just hiding them, use Power Query expressions to restrict the data source to only the subset that should be shared, and make sure aggregated views pull only from non-sensitive columns. Audit Power BI environments regularly for reports published to the web by accident.

|
Key Takeaways
|
What does cloud based live video production actually replace?
Traditional live production has historically depended on physical hardware: a dedicated video switcher, audio mixer, graphics system, and often a production truck to house it all. LiveU Studio represents a full shift away from that model, described as a 100% cloud-native, scalable live video production solution enabling live switching, audio mixing, customized overlays, graphics, remote guest management, and one-click distribution to up to 30 different, simultaneous digital destinations, all from a web browser rather than dedicated on-site hardware.
What does a cloud video switcher actually let a single operator manage?
A cloud video switcher consolidates what would traditionally require several specialized crew members and dedicated hardware stations into one browser-based interface a single operator can run. That includes instant replay, letting a production team relive game-changing moments with multi-angle replays and slow-motion playback, seamlessly replaying up to four camera angles in sync with a single click; ISO recording, capturing independent feeds from up to six cameras for post-production flexibility; and dynamic ad insertion, unlocking additional revenue streams across OTT and FAST platforms through automated marker insertion. A revamped, unified interface lets that single operator move quickly between switching, replay, and graphics on one screen, balancing speed and creativity even for demanding, fast-moving live events.
| Cloud switcher capability | What it replaces or simplifies |
|---|---|
| Live multi-cam switching | A dedicated hardware video switcher and the crew typically required to operate it. |
| Instant replay & ISO recording | Separate hardware replay systems and individual camera recording devices. |
| Remote guest management | Physical satellite or fiber links needed to bring a remote guest into a broadcast. |
| One-click multi-platform distribution | Manually configuring separate outputs for each individual streaming destination. |
What does an AI live production unit actually add at the point of capture?
While cloud production tools handle switching and distribution, a separate innovation is happening at the point of capture itself. The LU900Q intelligent production unit is the first field unit to natively integrate LiveU IQ (LIQ™), using AI-driven decision-making and smart operator selection to optimize connectivity in real time. Combined with integrated eSIM technology and optimized 5G modems, this AI-driven optimization keeps a unit connected reliably even in challenging locations like crowded stadiums or remote racetracks, without requiring a human operator to manually manage which network connection the unit is using at any given moment.
How does an AI live production unit actually make field production feel more like a studio?
Beyond connectivity optimization, an AI live production unit is designed to bring studio-level capability directly into field conditions. LiveU’s announcement of the LU900Q highlights dual video return and dual intercom as key additions, bringing the benefits of a studio environment directly to reporters working in the field. The unit supports single or dual-camera production workflows, transforming what used to be rigid broadcast setups into dynamic, adaptable production environments, while delivering 10-bit HDR 4:2:2 encoding with up to 32 audio channels for high-end productions requiring accurate geolocation and uncompromising performance.
How fast has investment in cloud video production actually grown?
The shift toward cloud-based production tools has accelerated sharply, driven substantially by the pandemic-era need for physically distributed production teams. Rethink Technology Research’s Cloud Production Technologies forecast projected global cloud production revenues would rise from approximately $601.87 million in 2020 to about $2.48 billion in 2026, more than tripling over six years, with sport identified as the single biggest driver of that growth. That trajectory reflects how thoroughly cloud-native tools have moved from an emergency pandemic workaround to a standard, ongoing part of how live productions actually get made.
How do a cloud video switcher and an AI live production unit actually work together?
- The field unit captures and transmits, using AI-driven connectivity optimization to maintain a stable feed regardless of changing network conditions.
- The cloud switcher receives and produces, handling live switching, graphics, and audio mixing entirely through a browser interface.
- Together they eliminate the need for on-site production trucks, since neither capturing nor producing the show requires dedicated hardware physically present at the venue.
- Both scale independently, letting a production team add field units or production capacity separately as a show’s requirements grow.
What does a modular, hybrid approach to cloud production actually mean for existing infrastructure?
Adopting cloud based live video production doesn’t necessarily mean abandoning existing hardware investments; a modular, hybrid ecosystem approach lets these components integrate with a current setup rather than requiring a full rip-and-replace transition. Combining field units delivering reliable, real-time feeds with cloud-native production tools lets a team scale output and engage more audiences across linear and digital channels using the same current staff and resources they already have. That modularity matters for organizations weighing a gradual transition, since it lets a production team adopt cloud switching for some shows or events while continuing to rely on existing hardware for others, rather than forcing an all-or-nothing decision before the benefits have been proven internally.
What should a production team weigh when deciding how much to shift toward cloud based workflows?
The right balance between cloud and on-premises production tools depends heavily on show complexity, team distribution, and existing infrastructure investment. A single-operator, multi-camera sports show with a distributed remote crew is a natural fit for a fully cloud-based approach, since the format’s flexibility advantages align directly with the production’s actual requirements. A large-scale broadcast with an already-built, deeply integrated on-site production truck may see less immediate benefit from a full migration, at least until that existing hardware genuinely reaches the end of its usable life. Evaluating the shift honestly, rather than assuming cloud production is automatically the right answer for every format, tends to produce better long-term technology decisions than following the industry trend uncritically.
Frequently Asked Questions
Do I need a production truck to use cloud based live video production?
No. That’s the core value proposition: cloud based live video production replaces the need for on-site hardware switchers and production trucks, since switching, graphics, and distribution all happen through a browser-based platform instead.
What makes a field unit qualify as an ‘AI live production unit’?
The defining characteristic is AI-driven decision-making applied directly to connectivity and production management, such as automatically optimizing which network connections to use in real time, rather than requiring manual operator intervention for those decisions.
Can a cloud video switcher handle a live sports broadcast with multiple camera angles?
Yes, a cloud video switcher built for this purpose supports fully synced multi-camera switching, instant replay across multiple angles, and independent ISO recording of each camera feed, covering the core requirements of a multi-camera sports production.
Why did cloud video production revenue grow so quickly between 2020 and 2026?
The COVID-19 pandemic accelerated adoption by forcing production teams to work from physically distributed locations, and sport was identified as the single biggest driver of that growth, given the format’s natural fit for remote, multi-camera cloud production.
|
Key Takeaways
|
Why does book binding determine how fast a collection can be digitized?
A large part of the cultural heritage community works on digitizing rare and delicate bound materials, and the binding itself is often what dictates how quickly that work can safely proceed. Phase One’s book digitization solutions are built around this reality directly: digitization of books often requires special attention to the binding, which can be fragile, and that fragility can become the limiting factor when an institution is looking for a fast capture turnaround. A binding that can’t be opened flat, for instance, rules out certain capture approaches entirely, regardless of how fast the camera itself can shoot.
How does a copy stand actually speed up the capture process?
Copy stands are the workhorse tool behind this entire workflow. Using a leveled glass plate with the camera set for fixed focus on a copy stand accelerates the capture process considerably, since the operator no longer needs to refocus or reposition for every single page. Photographing both pages of an open book at the same time, using one or two cameras, increases productivity further still. Institutions with valuable collections often maintain a dedicated photographic studio built around exactly this workflow, both to provide public access and research copies and to protect fragile originals from the wear and handling that repeated researcher access would otherwise cause.
How much faster is rapid-capture digitization than traditional scanning?
The gap between purpose-built digitization systems and conventional scanning equipment is large enough to change what’s realistically achievable for a big collection under time pressure. Fast, reliable digitization solutions built for transparent film and glass plate negatives can achieve a capture rate of roughly one image per second, up to 400 times faster than flatbed, drum, or virtual-drum scanners.
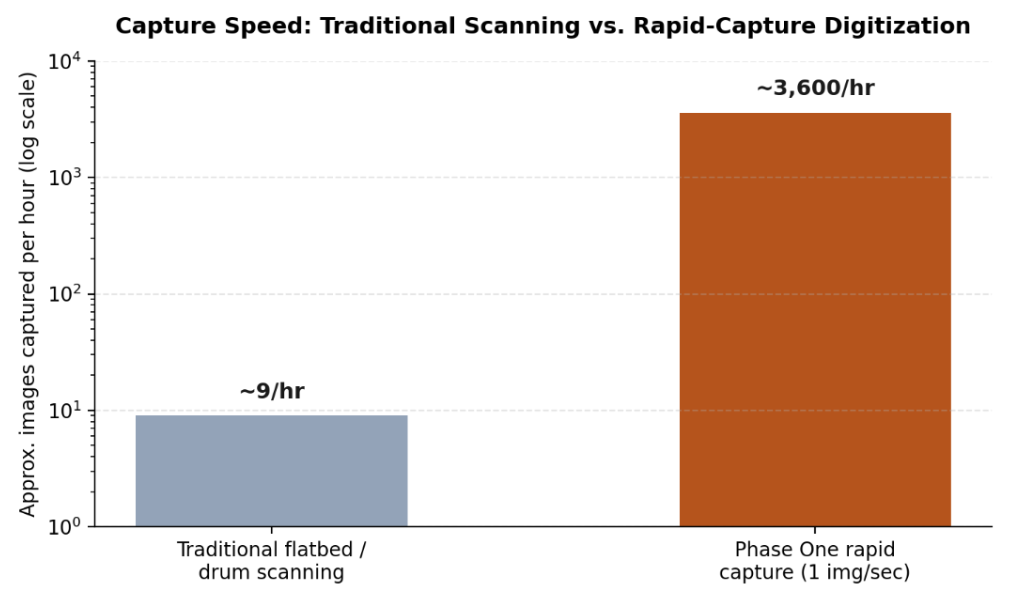
Approximate capture speed comparison between traditional flatbed or drum scanning and rapid-capture digitization (log scale).
That speed difference matters most because preserving the past is often a race against time: much of the material institutions are digitizing has a limited physical lifespan before it’s gone for good, so a workflow capable of moving through a large collection quickly can mean the difference between preserving a complete archive and losing part of it before the work is finished.
What copy stand configurations exist for different collection types?
| Copy stand type | Best suited for |
|---|---|
| Single-camera stationary stand | Smaller digitization projects needing a stable, long-lasting platform with one high-resolution camera system. |
| Dual-camera book system | Rare books that cannot be opened flat, using an automated dual-page capture workflow with two cameras. |
| AutoColumn large-format stand | Large, flat, and thin objects such as maps, newspapers, and drawings, with a metal cover board for secure magnetic positioning. |
| Motorized 2-motion stand | Larger flat objects requiring a bigger baseboard and flexibility across different lens configurations. |
What does digitizing the autochrome process actually involve?
Understanding the autochrome process itself helps explain why these plates need such careful handling. Autochrome plates, a color photography process that flourished from 1907 into the 1930s, present a distinct challenge inside cultural heritage digitization: each autochrome is a unique transparency image with no negative counterpart, meaning there is no duplicate to protect against a mistake during capture. Phase One’s film and glass plate digitization solutions address this class of material with a film capture stage that provides an adjustable, geared support mechanism compatible with a range of carriers built specifically for glass plate negatives, alongside most popular film strip and sheet formats. Glass plate carriers are made of milled high-grade aluminum with an optically-optimized glass base, built to hold plates of varying and sometimes irregular sizes securely and consistently during capture.
The conversion process for this kind of transparent, historical material is genuinely open to interpretation, since the base material and the chemical processing used varies, especially for the earliest glass plates where the specific chemicals and development process are often unknown. Two rolls of film, or two glass plates, may behave very differently, both in the physical characteristics of the original base material and in how that material was originally developed, which is part of why uniform, controlled illumination and consistent color reproduction matter so much throughout the capture process.
What does a well-run digitization workflow need beyond the camera and stand?
- Specialized workflow software: a rapid-capture solution paired with cultural heritage editing tools speeds up both capture and the post-production work of converting negatives to positives and correcting color.
- Simplified interfaces for large volumes: a streamlined capture mode allows less-specialized operators to handle high-volume digitization projects without sacrificing consistency.
- Accurate object identification: integrated barcode scanning during capture helps ensure every digitized object is named and tracked correctly across a large collection.
- Material-appropriate handling: different physical formats, bound books, flat documents, glass plates, each require their own specialized stand and carrier configuration rather than a one-size-fits-all setup.
What quality standards guide professional cultural heritage digitization?
Institutions digitizing valuable or fragile collections don’t simply capture an image and call it done; the output has to meet recognized quality benchmarks that ensure the digital copy is actually fit for long-term preservation and research use. Standards such as FADGI (the Federal Agencies Digital Guidelines Initiative), Metamorfoze, and ISO 19264 define specific technical targets for resolution, color accuracy, and tonal range, giving institutions a common language for specifying what “high quality” actually means in measurable terms rather than a subjective judgment. Meeting these benchmarks typically requires resolution around 300 pixels per inch or higher for most collection material, alongside carefully controlled, even illumination and accurate color calibration throughout the capture process.
| Standard | What it primarily governs |
|---|---|
| FADGI (Federal Agencies Digital Guidelines Initiative) | A star-rating system for image quality covering resolution, tonal response, and color accuracy, widely referenced across libraries and archives. |
| Metamorfoze | A Dutch national standard for image quality in cultural heritage digitization, with defined preservation and access quality tiers. |
| ISO 19264 | An international standard defining objective image quality analysis methods for cultural heritage reproduction. |
What happens to digitized material after capture?
Capture is only the first stage of a complete digitization program. Once an image is captured, it typically passes through post-production steps that can include cropping and alignment, negative-to-positive conversion for film and glass plate material, color correction against calibrated reference targets, and quality control review against whichever standard the institution has adopted. The resulting files are then usually stored in an uncompressed or losslessly compressed master format intended for long-term preservation, alongside smaller derivative files optimized for public access and online display. Metadata capture, recording what the object is, where it came from, and any relevant rights information, runs alongside this whole process, since a beautifully captured image with poor metadata is far less useful to future researchers than a properly documented one.
Frequently Asked Questions
Why can’t hidden or delicate bindings just be opened flat for faster scanning?
Forcing a fragile binding open flat risks damaging the book permanently. Digitization systems built for rare books instead use a dual-camera setup that photographs both pages simultaneously at whatever angle the binding safely allows, rather than forcing the book into a position that risks the original.
What makes autochrome plates harder to digitize than an ordinary photograph?
Each autochrome is a unique transparency with no negative, so there’s no backup if a plate is damaged during handling or capture. The plates are also physically fragile glass, and the exact chemical composition of early examples is often unknown, which makes consistent, accurate color reproduction more challenging than with a standard, well-documented film stock.
How much faster is rapid-capture digitization really, in practical terms?
Systems capable of roughly one image per second can be up to 400 times faster than flatbed, drum, or virtual-drum scanners, which can turn a project that would take months of scanning into one that takes days.
Does a copy stand work for objects other than books?
Yes. Different copy stand configurations exist for flat objects like maps and newspapers, for glass plate negatives and film, and for bound books specifically, each with hardware suited to that particular format’s handling and stability needs.
|
Key Takeaways
|
What is AI TRiSM, and why did Gartner define it?
AI TRiSM stands for AI Trust, Risk, and Security Management, a framework Gartner introduced to describe the technical capabilities organizations need to keep AI systems trustworthy, secure, and compliant, not just when they’re first deployed, but continuously as they operate. The framework’s core argument is that policies alone can’t keep up with how AI systems behave in production: risks emerge dynamically as models respond to new inputs, so governance has to be embedded directly into the systems themselves, through continuous monitoring, validation, and runtime enforcement, rather than relying on periodic review cycles.
Why is the AI TRiSM market growing so much faster than most security categories?
The growth rate here is unusually steep even by cybersecurity standards. MarketsandMarkets’ AI TRiSM market research projects the market will grow from $3.09 billion in 2026 to $11.61 billion by 2031, a compound annual growth rate of 30.3%, driven in large part by the shift from periodic AI assessments toward continuous control as enterprises deploy autonomous, tool-using AI agents. Within that broader market, the AI security and runtime protection platforms segment is forecast to grow even faster, at roughly 33.1% CAGR, which tracks closely with why runtime enforcement, not just governance policy, has become the fastest-moving part of this space.
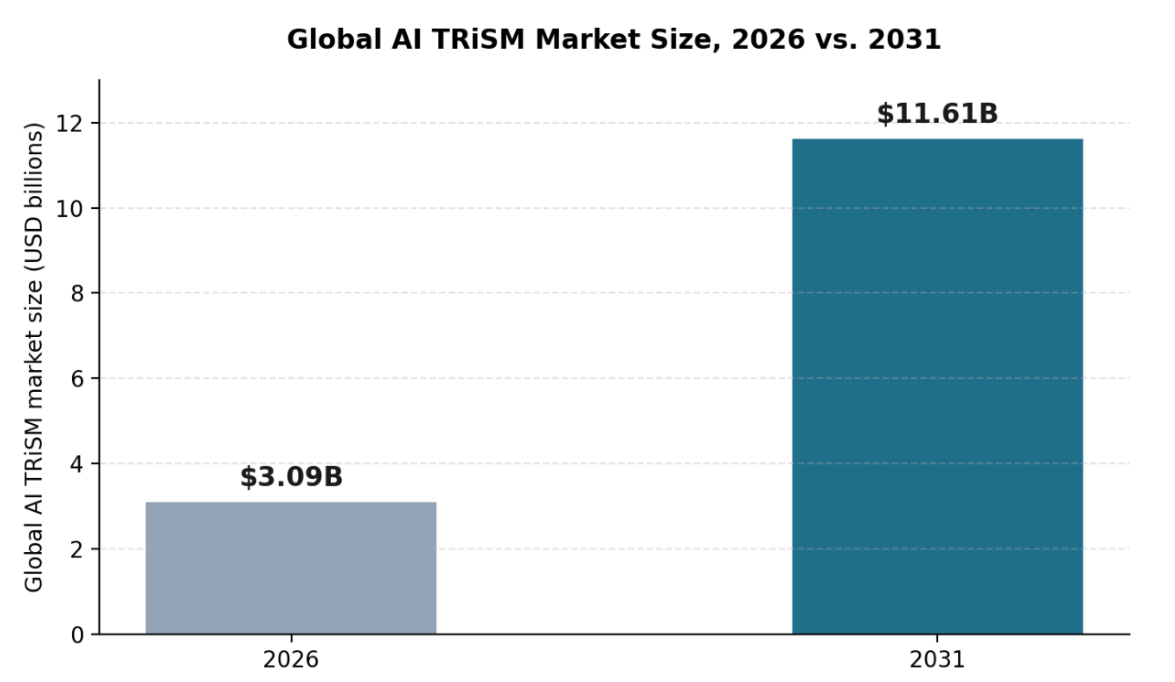
Global AI TRiSM market size, 2026 versus 2031, according to MarketsandMarkets.
What does an AI security platform actually need to cover?
| Pillar | What it covers |
|---|---|
| Discovery (AI-SPM) | A continuous, complete inventory of every AI application, agent, and tool operating across the organization. |
| Runtime protection (guardrails) | Input and output filtering that catches prompt injection, data leakage, and policy violations as interactions happen. |
| Agentic AI security | Visibility into agent decisions, tool calls, and data access, with enforcement that keeps autonomous behavior within intended scope. |
| Compliance & governance | Policy definition and audit-ready documentation mapped to regulations like the EU AI Act, GDPR, and industry-specific standards. |
The case for covering all four pillars from a single AI security platform, rather than four separate point tools, is largely operational: security teams need discovery findings to feed directly into policy enforcement, and agent behavior data to feed directly into compliance reporting, connections that are much harder to maintain across disconnected tools than within one shared system.
Why does agentic AI security specifically need its own attention?
A static chatbot answers questions; an autonomous agent takes actions, and that distinction changes the security calculus considerably. Ovalix’s autonomous and agentic AI security platform is built to give full visibility of AI agent tasks from start to finish, mapping out each decision so guardrails can be enforced and compliance maintained across AI-driven processes, rather than only reviewing outcomes after an agent has already acted. A closely related capability focused specifically on agent behavior safeguards AI agents from malicious manipulation, unauthorized control, and excessive autonomy, which matters because an agent with too much unchecked scope is a fundamentally different risk than a chatbot that simply gives a wrong answer.
What does ‘AI security software’ actually mean in practice?
In practice, the term increasingly refers to platforms consolidating what used to be handled by separate tools, or not handled at all, into one system: shadow AI discovery, data protection, runtime guardrails, and agentic oversight, unified under a shared policy engine and a single source of truth for what AI is running and what it’s doing. That consolidation trend mirrors what happened in adjacent security categories before it, where point solutions eventually gave way to platforms once the operational cost of stitching together separate tools outweighed the benefit of best-of-breed components for each narrow function.
Questions to ask when evaluating an AI security platform
- Does discovery run continuously, or only as a periodic scan that goes stale between runs?
- Does the platform cover agents as well as applications, including tool calls and autonomous decision chains, not just chatbot-style interactions?
- Are guardrails applied in both directions, filtering prompts going in and responses coming out?
- Does compliance reporting draw from the same data as enforcement, or does it require separately maintained records that can drift out of sync?
Frequently Asked Questions
Is AI TRiSM a specific product, or a framework?
AI TRiSM is a framework defined by Gartner, describing a set of capabilities organizations need, not a single named product. Different vendors, including AI security platforms, implement AI TRiSM’s principles in different ways.
Do small organizations need a full AI security platform, or just point tools?
It depends on the scale and complexity of AI usage, but even smaller organizations benefit from discovery and runtime protection working together, since the two feed each other: what you discover shapes what you need to enforce, and vice versa.
What’s the difference between AI security software and general cybersecurity software?
AI security software is purpose-built for risks specific to AI systems, prompt injection, model behavior monitoring, AI agent oversight, that general cybersecurity tools, built around network traffic and endpoint behavior, typically aren’t designed to catch.
Why is agentic AI considered higher risk than earlier generative AI tools?
Because agents don’t just generate text, they take actions and call tools, often chaining multiple steps together autonomously. That expands the potential consequences of a security gap well beyond what a single bad response from a chatbot could cause.
Tomato Breeders and the Push Toward Innovative Specialty Varieties
Cloud Based Live Video Production and the AI Live Production Unit
Book Digitization, Copy Stands, and Digitizing the Autochrome Process

-
 Business Solutions2 years ago
Live Video Broadcasting with Bonded Transmission Technology
-
 Business Solutions1 year ago
The Future of Healthcare SMS and RCS Messaging
-
 Business Solutions2 years ago
2-Way Texting Solutions from Company Message Services
-
 Business Solutions2 years ago
Communication with Analog to Fiber Converters & RF Link Budgets
-
 DSRC Communication1 year ago
The Crossroads of Connectivity: DSRC vs. C-V2X Technologies in Automotive Communication
-
 Business Solutions2 years ago
Wholesale SMS Platforms with OTP Services
-
 3D Technology1 year ago
How Multispectral Cameras Advance Book Scanning
-
 Business Solutions2 years ago
Choosing the Right B2B Digital Marketing Agency: A Guide